
Why Felix?
Most services end up needing three things at once: a record of what happened, the newest value for a key, and a way to hand work to whoever can do it. Felix is one system that does all three, because all three turn out to be the same thing read three different ways.
This page explains the idea without assuming you have read anything else here.
One job, three systems
Section titled “One job, three systems”Take an order service. It needs to:
- keep a record of what happened (order placed, paid, shipped, refunded) so other services can react to each event, and so you can replay the sequence later;
- answer “what is order 42 right now?” without walking that whole history;
- hand out work (send the receipt, charge the card) so that each job goes to exactly one worker and comes back if that worker dies.
Today that usually means three systems. Kafka or Redpanda for the record of what happened. Redis for the current value. NATS JetStream or RabbitMQ for the work.
All three are good at their job. Kafka holds years of history and replays it. Redis answers in microseconds and has data structures Felix does not have. JetStream and RabbitMQ have routing and delivery features built over a decade of people needing them. The rest of this section is about the cost of running all three together, not about any one of them being bad.
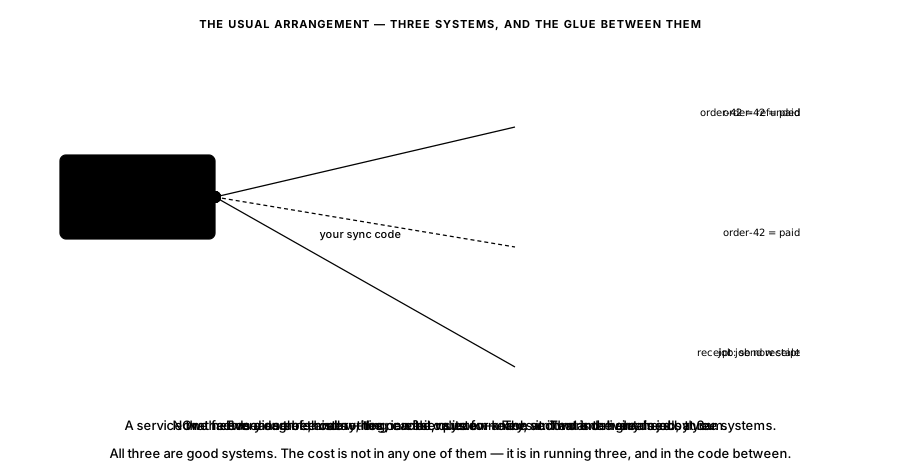
You have three deployments to install, upgrade and patch. Each has its own security model, so an identity has to be granted access three times in three different ways. Each replicates differently, fails differently, and has its own answer to “is it safe to restart this one?” Your team has to learn all three before running them becomes routine.
Then there is the glue code. When an order is paid, that fact has to reach both the log and the cache. That is two writes, and either can fail on its own. When the second one fails, the log says refunded and the cache says paid, and neither system is wrong from where it sits. Neither can even detect it. Only your code knows they were supposed to agree, which means only your code can notice, and only if you wrote that part.
What Felix does differently
Section titled “What Felix does differently”Felix stores one thing: an append-only log. A list of records where writes only ever land at the end, and nothing already written is ever changed.
Stream, cache and queue are three ways of reading that log.
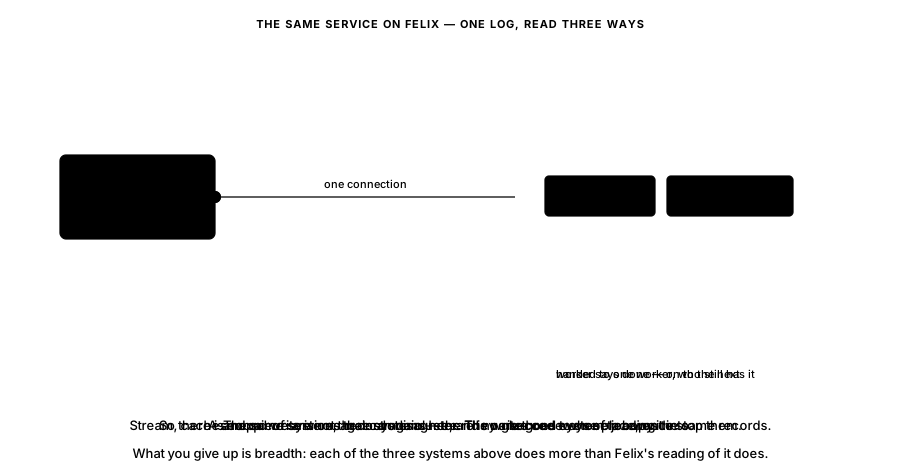
The write happens once. There is no second system to copy it into, so there is no pair of systems that can disagree, and no glue whose job was to stop them.
That single write is an atomic commit: one
call carries the event and the state that goes with it, and Felix stores them
as one record. Subscribers see the event, a consumer group gets it as work, and
a state read returns the new value, all at the same offset. A reader never sees
one without the other. A commit covers one stream’s shard; it is not a
transaction across shards. Felix’s standalone cache keeps its own log, so a
plain cache put next to a publish is still two writes.
Why one log can do all three
Section titled “Why one log can do all three”Picture the records in a line, oldest on the left. A new write is added on the right. Nothing already in the line ever changes.
Now put markers under that line. A marker is just a position: this is the record I am looking at.
- A stream is a marker that walks forward over every record, in the order they were written. A subscriber is just a position that keeps moving right.
- A cache uses one marker per key, and each one sits
on the newest record carrying its own key. Asking for the current value of
order-42means following that key’s marker and reading what it points at. The older records for that key are still in the line; the marker has just moved past them. - A queue is a marker shared by a group of workers that only moves when someone says a record is finished. That is why it trails behind the stream: it tracks what has been done rather than what has been written.
Two limits are worth knowing before you picture this working at scale. A subscriber that falls too far behind has records dropped rather than buffered for ever, and it is not told. On a durable stream the gap in the offsets shows it. That suits a live feed and is wrong for anything that must see every record without checking. And a group of workers reads one shard: if you split a stream across several, each shard gets its own group, and dividing the work between them is yours to arrange.
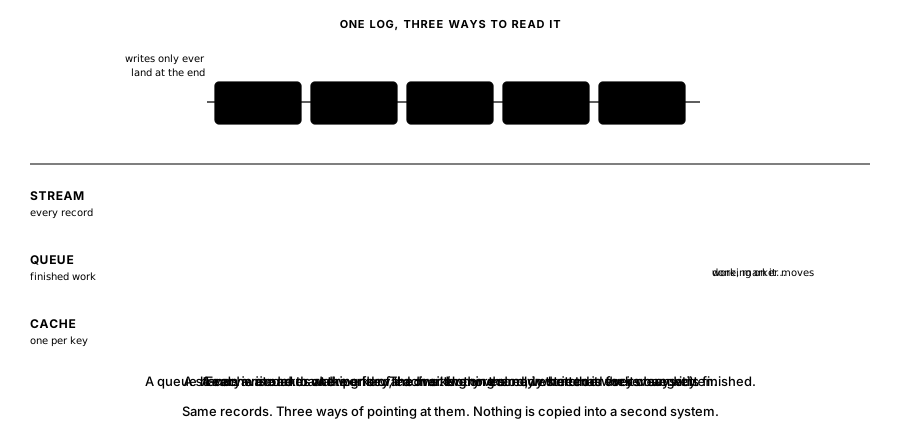
Nothing is copied into a second store, and no reading can disturb another. A worker finishing a job cannot move a subscriber’s position, and overwriting a key adds a record rather than destroying one.
The precise version of this, with the test behind each claim, is Projections.
What that gets you
Section titled “What that gets you”Because the three readings share one log, they share everything underneath it.
There is one system to deploy. In practice that means brokers plus a control plane, so two kinds of process, but one upgrade path and one set of release notes.
Access is granted per tenant and checked at the broker, and the same check covers publishing, subscribing and cache operations, so there is one place to reason about who can reach what.
A cache shard is replicated by the same code that replicates a stream, because it is the same log. There is one answer to “is this write safe yet?” The same goes for recovery: one way a node comes back, one way a torn write at the end of a file is repaired, and one meaning for “this record is on disk.”
Configuration, metrics and failure modes are also shared, so there is less to learn. When you get paged at 3am, it is about one system with one dashboard you already know, and two systems cannot quietly disagree about the same fact.
It speaks Kafka too
Section titled “It speaks Kafka too”You do not have to rewrite every client to try it. Each broker can run a Kafka
listener, and a durable stream then looks like a Kafka topic: partitions are
shards and offsets are Felix’s own. Existing Kafka producers write to it,
idempotent ones included, and a consumer that assigns its own partitions reads
from it, so kcat and librdkafka programs can be pointed at Felix one at a
time while the rest of a system moves over. (The Java client is not tested yet.) What it does not speak is
anything built on consumer groups or transactions; that limit is spelled out
under When not to use Felix, and the details are in
Kafka compatibility.
When not to use Felix
Section titled “When not to use Felix”-
You already run Kafka in production. It works, your team knows it, and the operational cost you would save is a cost you have already paid. Replacing working infrastructure to reduce system count is rarely worth it.
-
You need the Kafka ecosystem. Felix speaks enough Kafka for producers and for consumers that assign their own partitions, which covers plenty of hand-written services. It does not speak enough for the ecosystem. Kafka Connect, Streams, ksqlDB, Debezium and MirrorMaker all run on consumer groups or transactions, and Felix refuses both on purpose. If you need those tools, use something that speaks the whole protocol.
This is deliberate. Building a group coordinator means building a rebalance protocol Felix deliberately does not have and owning its behaviour across Kafka versions. Instead, Felix answers a group consumer with an error that says so, rather than leave it hanging in “waiting for group rebalance”. The details, including what other Kafka-compatible systems had to build, are in
docs/kafka-compatibility.md. -
You need AMQP. Exchanges, bindings, topic routing, per-message TTL, priority queues: Felix has none of the RabbitMQ model. A queue in Felix is a group of workers reading one shard, and nothing more.
-
You need Redis data structures. Felix’s cache is the newest value for a key, with an optional expiry, plus counters. No lists, sets, sorted sets, hashes, streams, scripting or pub/sub channels. If you use Redis for anything beyond “remember this value,” Felix is not a replacement for it.
-
You need long-term history. There is no tiered or cold storage. Retention is bounded by the disks you give the brokers.
-
You need production mileage. Nobody has run Felix in production. If your answer to “who else runs this?” has to be a name, the answer today is nobody.
Felix is worth considering when you are building something new, you can see all three needs coming, and you would rather learn one system than three. It is not worth considering as a replacement for three systems that are already working.
Where it stands
Section titled “Where it stands”Felix is pre-1.0 and in active development.
What exists today: multi-broker clusters, a durable log with crash recovery, replication with fenced failover and majority acknowledgement, online rebalancing (live shard moves, drain and join), a cache with expiry and counters, consumer groups with acknowledgements and redelivery, a control plane over REST, and tenant-scoped tokens with OIDC token exchange.
What does not exist yet:
- Per-stream retention. A policy can be recorded on a stream, but nothing reads it. Retention itself works, but it is configured per broker and is off unless you set it, so by default a log grows until the disk does.
- Load-aware placement. Rebalancing evens out shard counts, not load, so a broker leading its share of hot shards is left as it is.
- Tiered storage, cross-region bridges, encryption at rest, and audit logging.
- Clients beyond Rust, Python and TypeScript.
For the detail on each capability (shipped, partial, or only intended), read What Felix Is For. It is kept current per capability and it is the page to trust when another disagrees with it.
- What Felix Is For: the status table and where Felix fits
- Use Cases: concrete scenarios, with code and how each compares with other brokers
- Quickstart: run a broker and publish something
- Projections: the precise version of how one log is read three ways