
System Design
How the whole system fits together: the design goals, the pieces, and the paths a publish, a subscribe, and a cache request take through them.
Design Principles
Section titled “Design Principles”1. One Core Log, Many Semantics
Section titled “1. One Core Log, Many Semantics”Internally, Felix is built around a single append-only log abstraction. Different external semantics are projections over this core:
- Streams (Pub/Sub): read the log forward, one cursor per subscription
- Caches: read the log through an index of key to latest offset, rebuilt from the log itself
- Queues: read the log through a cursor shared by a consumer group, with acknowledgements and bounded redelivery
All three are built. What each one stores, keeps in memory, and rebuilds from the log, along with the test behind each claim, is in Projections. Trust that page where this one is vaguer.
This reduces operational complexity and consistency bugs compared to running Kafka, Redis, and a queueing system side-by-side. It is also the project’s central bet, so the claims are tied to tests: scripts/check_doc_evidence.py fails the docs build if a cited test no longer exists.
2. Low-Latency First
Section titled “2. Low-Latency First”Felix prioritizes predictable low latency over maximum batch throughput:
- QUIC transport: Multiplexed, encrypted, congestion-aware
- Optional ephemeral streams: No disk on hot path
- Aggressive backpressure: Bounded memory everywhere
- Leader-based writes: Tunable acknowledgement policies
3. Kubernetes-Native
Section titled “3. Kubernetes-Native”Felix assumes Kubernetes for process lifecycle, identity (ServiceAccounts), networking and service discovery. Felix does not reimplement scheduling. Broker membership is Felix’s own: brokers register with the control plane and heartbeat, and a broker unheard for FELIX_NODE_EXPIRY_TIMEOUT_MS (15 s by default) is marked down and its shards are placed elsewhere.
System Architecture
Section titled “System Architecture”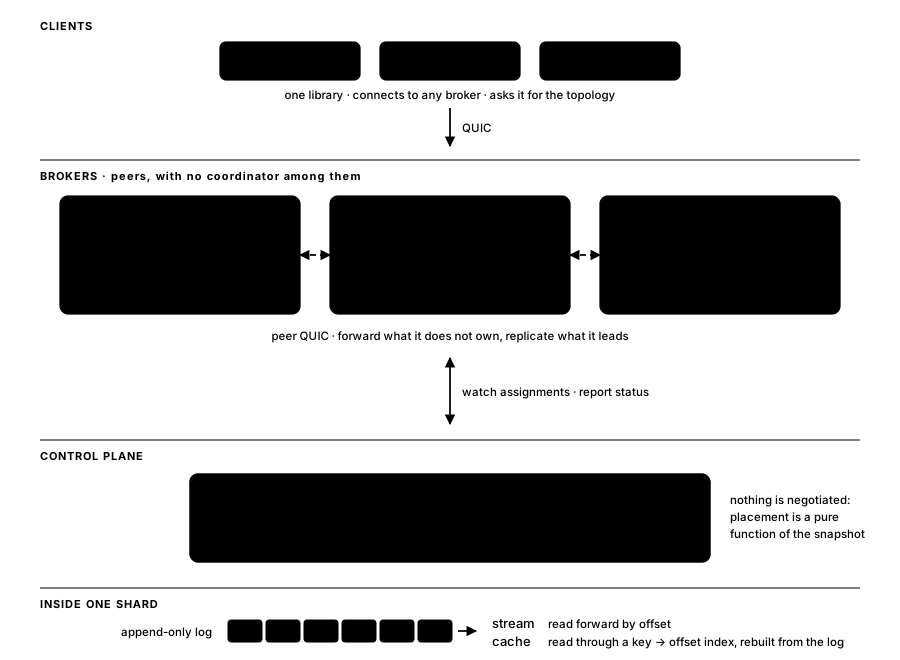
Three things carry most of the design.
Any broker accepts any request. A client connects to whichever broker it can reach and asks it for the topology. If that broker does not lead the shard the request belongs to, it forwards the request to the broker that does and relays the answer. The client never has to find the right broker first, and talks to only one broker per request.
Ownership comes from the control plane, and only from there. Every shard of every stream and cache has exactly one leader, chosen by rendezvous hashing over the live nodes, and its followers are spread across the zones brokers register (FELIX_NODE_ZONE) wherever a broker in a missing zone has room. Brokers watch the assignment feed (a snapshot, then a change stream) and never negotiate ownership among themselves. When a shard has to move, because its broker is draining or leads more than its share, the control plane stages the destination as a replica, fences the leader once the copy is level, and only then names the destination, so a shard is never served by a broker that has not seen its log (see Adding, draining and removing brokers).
No consensus protocol runs between brokers. Placement is deterministic over the rows it reads, and control-plane instances do not coordinate a shared snapshot: every assignment write is conditional on the generation and placement token it was planned from, so a write planned from stale reads is refused. Durability across a leader change comes from log shipping, leader leases, and the fence a promoted stream leader takes on a majority of its replicas before it serves. Per-shard Raft was considered and rejected, for reasons set out in docs/replication-design.md.
That rejection is specific to replicating records. Making the control plane’s own metadata highly available is a separate problem, and Raft is the answer there: the instances embed a Raft group and hold the metadata themselves, with no external database. See Metadata Raft; Postgres remains fully supported for deployments that prefer it.
The control plane is off the data path for reads, subscribes, and Leader publishes: brokers read it in the background and serve from what they already hold.
A Quorum publish is the exception. It is released by the shard’s quorum mark, and the leader sends its replica report to the control plane before moving that mark and waits for the answer. Otherwise a leader could tell a client its record is on a majority while the control plane still knows nothing about which replica holds it, and a leader dying in that window is replaced by whichever replica scores highest, possibly the one without the record. So a quorum acknowledgement costs one control-plane round trip, and an unreachable control plane stalls Quorum publishes rather than acknowledging on a report that never landed. Once the fleet finalizes majority_ack, a Quorum stream drops that round trip: the followers’ answers at the leader’s generation decide the acknowledgement, the report goes out behind the mark for placement only, and every promoted leader fences a majority before it serves, which is what keeps an acknowledged record without the report.
Control plane
Section titled “Control plane”Serves metadata over REST, backed by a Raft group across the instances, by Postgres, or by an in-memory store. It owns tenants, namespaces, streams, caches, the node catalog, and shard assignments, and it runs placement on a timer. Brokers seed from it at startup and gate readiness on that seeding, so a broker does not accept traffic for streams it does not yet know about.
Data plane
Section titled “Data plane”Brokers serve clients over QUIC and reach each other over a separate QUIC endpoint with its own protocol. Each one leads some shards, replicates the ones it leads to followers, forwards what it does not lead, and refuses what it cannot route. A request served locally by a broker that does not own it is the divergence the ownership check exists to prevent.
A broker can also run a Kafka listener beside its QUIC one. It is a second front door onto the same shards: a Kafka produce goes through the broker’s own publish path on the shard’s leader, and a fetch reads the shard’s log by offset. Unlike QUIC requests, Kafka requests are never forwarded; Kafka clients find a partition’s leader through Metadata and go to it themselves. See Kafka compatibility.
Data Flow Patterns
Section titled “Data Flow Patterns”Publish/Subscribe Flow
Section titled “Publish/Subscribe Flow”sequenceDiagram
participant P as Publisher
participant B as Broker
participant S1 as Subscriber 1
participant S2 as Subscriber 2
P->>B: Open control stream (QUIC bi)
S1->>B: Open control stream (QUIC bi)
S2->>B: Open control stream (QUIC bi)
S1->>B: Subscribe(tenant, namespace, stream)
B-->>S1: OK
B->>S1: Open event stream (QUIC uni)
S2->>B: Subscribe(tenant, namespace, stream)
B-->>S2: OK
B->>S2: Open event stream (QUIC uni)
loop Publishing
P->>B: Publish(batch of messages)
B-->>P: ACK (optional)
B->>B: Enqueue for fanout
par Fanout to subscribers
B->>S1: Event batch
B->>S2: Event batch
end
end
Properties of this flow:
- Publishers use bidirectional control streams for publish requests
- Subscribers get dedicated unidirectional event streams
- Fanout happens independently per subscriber (isolation)
- Batching is time and count-bounded for throughput optimization
Cache Flow
Section titled “Cache Flow”sequenceDiagram
participant C as Client
participant B as Broker
C->>B: Open cache stream pool (N connections)
Note over C,B: M stream workers per connection
par Concurrent requests
C->>B: cache_put(tenant, namespace, cache, key1, value1, ttl)
C->>B: cache_get(tenant, namespace, cache, key2)
C->>B: cache_put(tenant, namespace, cache, key3, value3, ttl)
end
par Concurrent responses
B-->>C: OK (key1)
B-->>C: cache_value(key2, null)
B-->>C: OK (key3)
end
Properties of this flow:
- Connection pooling reduces handshake overhead
- Request multiplexing over long-lived streams
- Request IDs for request/response matching
- Sub-millisecond latency at moderate concurrency
Cross-Broker Routing
Section titled “Cross-Broker Routing”When a client reaches a broker that does not lead the target shard:
sequenceDiagram
    participant C as Client
    participant B1 as Broker (ingress)
    participant B2 as Broker (shard owner)

    C->>B1: Publish(stream, key, batch)
    B1->>B1: hash the key, resolve the owner locally
    B1->>B2: AuthorizedForwardPublish(shard, generation, payloads, client credential)
    B2->>B2: check ownership at that generation, verify the credential, then commit
    B2-->>B1: ForwardPublishOk(offsets)
    B1-->>C: Ack
The control plane is not involved. Resolving an owner is an atomic load of a routing snapshot the broker already holds, with no lock and no network call, because this is the question the broker is asked most often. The snapshot is refreshed in the background from the assignment feed.
Streams created once the fleet has finalized jump_hash_routing map keys to
shards with jump consistent hashing. Older streams keep the modulo mapping they
were created with.
The generation the ingress broker resolved against travels with the request.
The owner compares it against its own and answers a mismatch explicitly in either
direction, so a stale view is a typed answer rather than a write to a shard
somebody has already been given. Once streams and caches have incarnations, the
request also names the incarnation its route was for, and the owner refuses one
routed by a deleted stream’s assignment even at the same generation.
Storage Architecture
Section titled “Storage Architecture”Storage is selected per stream. A stream registered with durable: false (the
default) stays in memory; durable: true writes every publish
to disk before it is fanned out or acknowledged.
Ephemeral (default)
Section titled “Ephemeral (default)”- In-memory only: No disk writes on hot path
- Bounded buffers: Ring buffers with fixed capacity
- TTL support: Lazy expiration on access
- No persistence: Data lost on restart
Use cases:
- Latency-sensitive workloads that can lose data on restart
- Development and testing
- Temporary caching
- Non-critical event streams
Durable (durable: true)
Section titled “Durable (durable: true)”- Segmented append-only log: versioned, checksummed segments per stream shard, with sparse offset indexes. This is not a write-ahead log: the log is the data, not a journal protecting another structure.
- Configurable fsync:
none,periodic { interval }, oron_commit, which acknowledges only after the record is on the device - Crash recovery: a provably incomplete tail is repaired; anything else fails startup loudly rather than discarding acknowledged records
- Historical replay: paged reads from disk by offset
Retention is implemented and off by default: set a stream’s retention, or
FELIX_DURABLE_RETENTION_BYTES or FELIX_DURABLE_RETENTION_SECONDS for every
stream that sets none, and the oldest segments are discarded, with a resume below the oldest retained offset
answered by a typed error rather than a silent restart at the tail. Unset,
nothing deletes segments and a log grows without bound.
Tiered storage is partial (#172):
with FELIX_DURABLE_OFFLOAD_DIR set, sealed segments are copied to a directory
before retention deletes them, but nothing reads the copies back yet. Stream
snapshots are not implemented. Compaction exists, but for
the cache rather than for streams: a cache log reclaims superseded and expired
records, and a stream log never rewrites a record at all.
See Durable Storage.
Use cases:
- Production event streaming
- Critical message delivery
- Replay and audit trails
Consistency Model
Section titled “Consistency Model”Single node
Section titled “Single node”- Delivery: At-most-once for a plain subscription; at-least-once through a consumer group, which redelivers anything not acknowledged before its visibility timeout
- Ordering: Per-stream ordering preserved per subscriber. For a durable stream, the order on disk is authoritative and cursor replay and live delivery both follow it.
- Durability: Per stream. Ephemeral by default;
durable: truepersists every publish before acknowledging it.
Clustered
Section titled “Clustered”Consistency is declared per stream:
Leader: the leader acknowledges once the record is durable locally. Lowest latency, and the default.Quorum: the leader waits until a majority of the shard’s replicas (itself included) hold the record. A record acknowledged this way survives the loss of its leader.
A leader serves only while it holds a lease on the shards it leads, so a broker that has been superseded stops acknowledging rather than discovering the fact later.
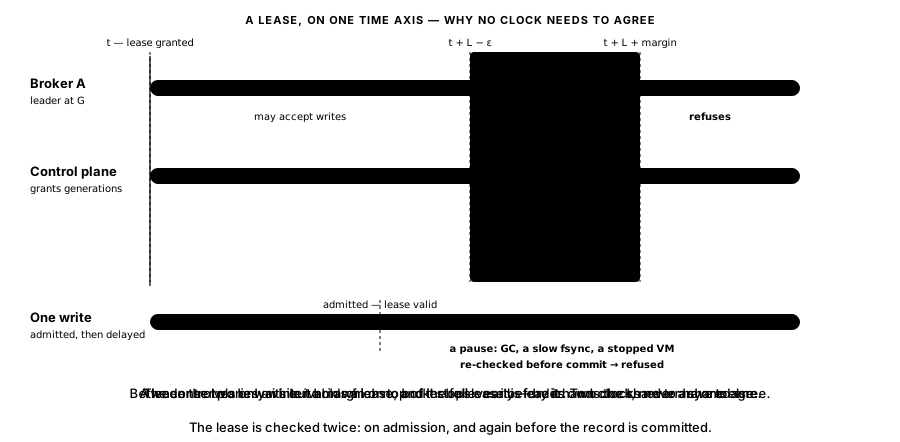
The leader stops ε early by its own clock; the control plane waits out a
margin on top of the full lease before handing the shard to anyone else. The
gap between those two instants is a safety interval in which no broker believes
it is leader. That is why this works without the two clocks ever agreeing:
each only has to measure its own elapsed time. Each side keeps a quarter of the
lease (FELIX_NODE_REGRANT_MARGIN_MS is the control plane’s, and cannot be set
lower), and the control plane measures the silence on its own monotonic clock,
so a wall-clock step cannot shorten it.
The lease is checked twice, on admission and again immediately before the record
is committed. The second check matters because a full ingress queue, a slow
fsync or a stopped VM can take arbitrarily long, and a lease that was valid when
the request arrived may have expired by the time the bytes reach the disk. On failover, only a replica that actually holds the log is promoted: a
shard whose leader is gone and whose replicas are behind is left unavailable
rather than reopened empty, because a silently empty shard is the data loss.
Once the fleet has finalized generation_start, every new leader of a durable
stream shard or a cache shard, promoted or moved in, writes a generation-start record before it
serves and counts a majority toward its quorum mark only from there, so it never acknowledges an
inherited record that a later promotion could replace (Raft’s Figure 8). Once
it has also finalized majority_ack, a Quorum stream’s writes need no lease
at all: admission, commit and acknowledgement go by the followers’ answers,
and with fenced_caches too so do a Quorum cache’s puts and counter adds,
whose promoted shards fence their cache and counter logs before they serve.
Only Leader streams and caches, and reads, still stop when the lease lapses.
With lease_free_reads finalized as well, Quorum cache reads confirm
leadership read-index style instead: one round of fences at the leader’s own
generation, answered by a majority after the read took its value. Readers of a
replicated Quorum shard (subscriptions, replay, Kafka fetches, cache watches)
then keep going through a lapsed lease and end only once the broker learns it
was replaced or loses its majority, and consumer-group writes are confirmed by
the same round before they are acknowledged. The round
vouches for leadership, not for the value, so a cache write the leader’s
storage refuses is answered as an error rather than acknowledged. A broker
started with FELIX_QUORUM_READS=lease keeps its reads on the lease.
Delivery guarantees:
- At-most-once: a plain subscription, best-effort with no retries
- At-least-once: a consumer group, which redelivers until acknowledged and then dead-letters; or a durable stream replayed from a checkpointed offset
- Exactly-once: not implemented, and not planned. See Semantics
Multi-Region Architecture (Planned)
Section titled “Multi-Region Architecture (Planned)”The target design has Felix enforce regional isolation with explicit bridges:
flowchart LR
    subgraph Region1["Region: US-EAST"]
        B1["Brokers<br/>US-EAST"]
        CONTROLPLANE1["Control Plane<br/>US-EAST"]
    end

    subgraph Region2["Region: EU-WEST"]
        B2["Brokers<br/>EU-WEST"]
        CONTROLPLANE2["Control Plane<br/>EU-WEST"]
    end

    subgraph Bridge["Explicit Bridge"]
        BridgeAgent["Bridge Agent<br/>• Allowlist<br/>• Encryption<br/>• Audit Log"]
    end

    B1 <-->|"Explicit config only"| BridgeAgent
    BridgeAgent <-->|"Explicit config only"| B2

    style Region1 fill:#e1f5ff,stroke:#334155,color:#111827
    style Region2 fill:#fff4e1,stroke:#334155,color:#111827
    style Bridge fill:#ffe1e1,stroke:#334155,color:#111827
Target bridge characteristics (not yet built):
- Explicit Configuration: No implicit data movement
- Stream Allowlist: Only specified streams replicate
- Independent Encryption: Per-region key contexts
- Audit Trail: Complete log of cross-region data movement
None of this has been implemented or audited; do not rely on it for regulatory or compliance purposes until it ships.
Scalability Considerations
Section titled “Scalability Considerations”Vertical Scaling (Single-Node)
Section titled “Vertical Scaling (Single-Node)”- CPU: More cores for parallel stream processing
- Memory: Larger buffers and cache capacity
- Network: Higher bandwidth for fanout
- Measured: hundreds of thousands to millions of msg/s on a single node, depending on payload size and fanout. See Benchmarks for measured figures
Horizontal Scaling (Multi-Node)
Section titled “Horizontal Scaling (Multi-Node)”- Sharding: Partition streams across brokers
- Connection pooling: Reuse connections across shards
- Control plane: REST over Raft, Postgres, or memory; scale by adding instances, since placement writes are conditional and need no agreement between them. On the Postgres backend the instances are stateless; on the Raft backend they hold the metadata themselves
- Data plane: many broker nodes for capacity
No cluster-level throughput figure is claimed here: the published benchmarks are single-node, and a multi-node number measured on one machine would say more about the loopback than about Felix.
Next Steps
Section titled “Next Steps”- Components Deep Dive - Detailed component architecture
- Wire Protocol - Protocol specification
- Semantics - Delivery and consistency guarantees
- Performance Tuning - Optimize for your workload