
Projections
Felix stores everything in one kind of thing: an append-only log of records, split into shards, each shard owned by one broker and replicated to others. A semantic is a way of reading that log. Streams, caches and queues are three readings of the same bytes.
This page says what each one stores, what it keeps in memory, and what it
rebuilds from the log, and cites the test behind each claim. A claim here
without a citation is one nothing checks. scripts/check_doc_evidence.py verifies that every test
named below still exists.
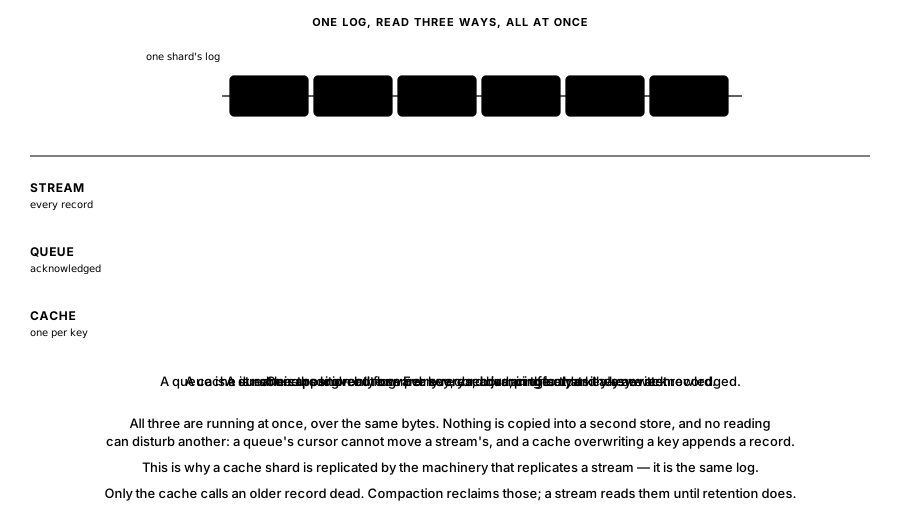
A stream, a queue and a cache are three ways of pointing into one log, and they run at the same time over the same bytes:
- a stream marker sweeps every record, in the order it was written;
- a queue marker covers the same records but trails, because it moves only as records are acknowledged;
- a cache is one marker per key, each jumping to that key’s newest record and leaving the older ones behind.
So only the cache treats an older record as dead. Compaction reclaims those; a stream reading the same log still returns them, until retention removes the segment they live in. Nothing is copied into a second store, and no reading can disturb another.
What they share
Section titled “What they share”Every semantic gets the same four things from the log, and none of them reimplements any of it:
- Durability. Records are fsynced according to the stream’s policy, and a record acknowledged as durable is on disk.
- Recovery. A torn tail is repaired at startup; interior corruption refuses to start rather than silently losing acknowledged records.
- Placement and routing. Every shard of every stream and cache has one leader, chosen by rendezvous hashing. A broker that receives a request for a shard it does not lead forwards it or refuses.
- Replication. The leader ships records at their offsets; a follower checks each batch begins at its tail.
A new leader writes a generation-start record before it serves. It takes an offset, and every reading below skips it. Only replication ships it.
a_cache_value_survives_the_loss_of_its_owner: a cache shard is replicated by the machinery that replicates a stream, because it is the same log.
Streams: read the log forward
Section titled “Streams: read the log forward”The plainest reading. A subscriber holds an offset and moves through the log in order.
- In the log: the records, as published.
- In memory: per-subscriber queues with an overflow policy, and the offset each subscriber has reached.
- Rebuilt from the log: nothing needs to be. A subscriber’s position is supplied by the client, so a broker holds no derived state a restart could lose.
Ordering is per shard. Two records in one shard are delivered in the order they were written; two records in different shards have no order between them, because they are different logs.
a_publish_to_a_non_owner_is_still_forwarded: a publish entering any broker reaches the shard’s owner.
Caches: read the log through a key index
Section titled “Caches: read the log through a key index”A cache write is an append. A cache read is an index lookup followed by a read at that offset.
- In the log: one record per put and per delete, each carrying the key.
- In memory: an index of key to the offset of its latest record, plus the bytes each record occupies, so compaction knows when it is worth running.
- Rebuilt from the log: the whole index. Compaction leaves a snapshot of it on disk, which an open uses only after checking it against the log, to replay just the records past it. It catches up to the log’s tail whenever it is behind. That lets a promoted follower serve records that arrived by replication instead of through a put.
Compaction copies the live set forward and drops superseded and expired records. It appends the live set at the tail rather than renumbering from zero, so an offset names the same record for the life of the shard, then deletes the sealed segments below the point it copied from. It runs on a background task with its own I/O budget, so no write waits for it, and a crash anywhere in a pass replays to the same cache.
a_cache_survives_a_restart: the index is rebuilt from the log.the_index_catches_up_with_records_appended_behind_it: records that arrive without going through a put are still found.compaction_does_not_rewind_the_offset_space: an offset keeps its meaning.a_deleted_key_stays_deleted_across_a_restart: a tombstone is a record like any other.
Queues: read the log through a shared cursor
Section titled “Queues: read the log through a shared cursor”A consumer group is a position in the log shared by its consumers, plus the bookkeeping for what is currently handed out.
- In the log: nothing of the group’s own. The records are the stream’s.
- On disk, beside the log: the group’s committed position, and the offsets it has given up on. Both are key-to-latest-value projections, the same reading the cache uses, on their own roots.
- In memory: what is handed out and to when, what is owed, and how many times each unsettled record has been tried.
The in-memory part is deliberately not durable. A leader that dies loses it and the group resumes from its committed position, so those records are delivered again. That is at-least-once, the guarantee a queue offers anyway.
a_position_survives_a_restart: the committed position is durable.an_offset_in_flight_is_not_handed_out_again: one consumer holds a record at a time.a_lapsed_claim_is_handed_out_again: a consumer that stops answering does not hold a record for ever.the_cursor_does_not_advance_over_a_gap: the position moves only over a contiguous run of acknowledgements.a_record_is_given_up_on_after_the_attempt_bound: one poison record does not stop the queue.only_the_shard_owner_serves_a_group: two brokers cannot both hand out the same records.a_group_position_survives_a_leader_failover: a promoted leader resumes where the group had got to.a_dead_letter_survives_a_leader_failover: and it still lists what that group gave up on.
Both of those travel together. The offsets a group abandoned are one log per stream shard, with the group folded into the entry key exactly as the cursors are, so they ship beside the cursors on the same replica set at the same generation. A promoted leader lists what its groups set aside, and an operator’s redrive works there.
What a queue does not promise
Section titled “What a queue does not promise”Order. A shared cursor gives it up the moment two consumers hold adjacent records, and a redelivery reorders regardless of how many consumers there are. A queue in Felix preserves the order records were handed out in, and nothing about the order they are finished in.
A consumer per group. A group is bound to the shard the caller names, and nothing assigns shards across a group’s consumers. Scaling one past a single consumer per shard is the application’s job today.
Exactly-once. A record can be delivered twice: after a claim lapses, after a leader is lost, or after a redrive. Every consumer has to be able to see the same record again.
Where this stops being true
Section titled “Where this stops being true”The claims above are the ones with tests. These are the known gaps:
- Retention outranks a group. A record trimmed before a group reached it is skipped, and the group moves past. A retention window shorter than a group is allowed to fall behind loses work.
- Dead letters in a per-group log do not travel. Dead letters ship in one
log per stream shard, which the replication driver walks. A per-
(stream, group)dead-letter log is still read and still discardable, but the driver cannot enumerate those logs, so it never ships them. On a shard carrying one, a failover keeps the group’s cursor and loses those set-aside records.